Telling Technology · Learning in public
Client & enterprise work

Shipped AI systems.
Real companies.

Built inside real client organisations: knowledge wikis, dashboards, governance, chatbots. Each case shows the problem, the system, and the value — and the list grows as new work ships.

Screenshots are anonymized demos (fictional brand, synthetic data); the systems are real. The channel’s own systems are the Builds further down. The method: Constraints removed, KPIs moved.

Customer testimonials

References willing to speak for us

Quotes are published only with each person’s written approval — name and role, never company names. More are being collected.

“Jacob turned our TechDoc output into a searchable, bilingual wiki. The AI caught template leaks, cut re-publish review time, and surfaced gaps nobody had flagged. Everything we’ve built with AI since rests on that foundation.”

“Jacob set up single sign-on for three of our internal tools through a proper Microsoft Entra app registration, so only our own company accounts get in. He also built the publishing pipeline — push to GitHub, Azure deploys it automatically, no build servers to babysit. And he got every permission and secret wired correctly so it worked end to end.”

“Compliance documents used to eat a full day each — Borehole and M&E specs, RIBA Stage 4 reports, all built by hand against UK Building Regs, HNTAS and CP1 citations. Jacob built a tool where I pick the document type, toggle the sections I need, and get a live preview as I go. What took a day now takes an hour, and the export is ready — PDF or Word.”

Customer

Nordpump · Nordic heat-pump manufacturer

Anonymized stand-in brand for a real industrial product company. Eight systems shipped, four scoped on the roadmap below. All names and data on the screens are synthetic.
Problem
What we built
Value
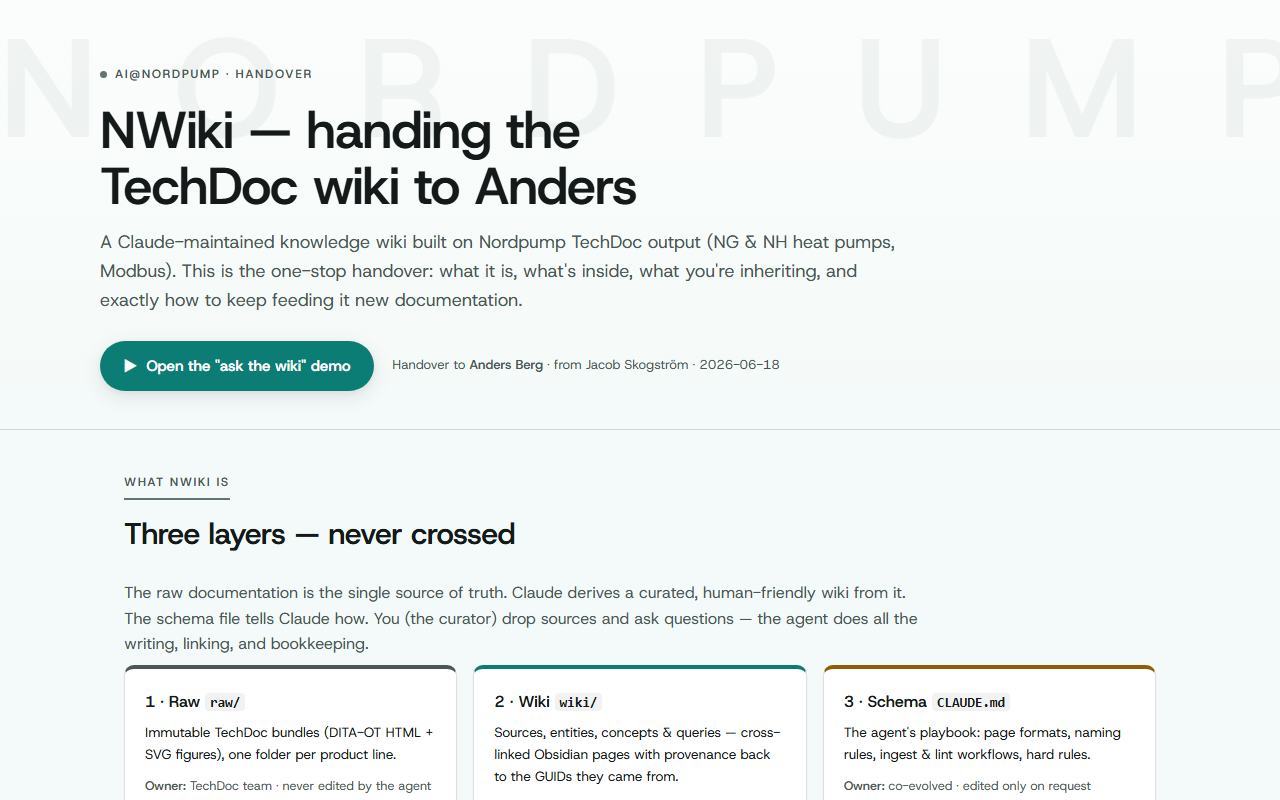
Knowledge-wiki handover page showing the three-layer raw/wiki/schema architecture anonymized demo
Case 01 Documentation

Product Knowledge Wiki

Product knowledge was locked in siloed PDFs nobody could search.

Problem

Technical installation manuals and product specs lived as scattered PDFs — hard to search, impossible to cross-reference, not translated.

Value

Institutional product knowledge made searchable, reusable and translation-ready — the backbone every downstream AI project built on.

What we built

Turned all documentation into a structured wiki with cross-linked entity and concept pages, embedded technical diagrams, and a bilingual EN/SE terminology set.

structured wiki cross-linked entities EN/SE terminology
“Jacob turned our TechDoc output into a searchable, bilingual wiki. The AI caught template leaks, cut re-publish review time, and surfaced gaps nobody had flagged. Everything we’ve built with AI since rests on that foundation.” Niklas · Technical Documentation Manager
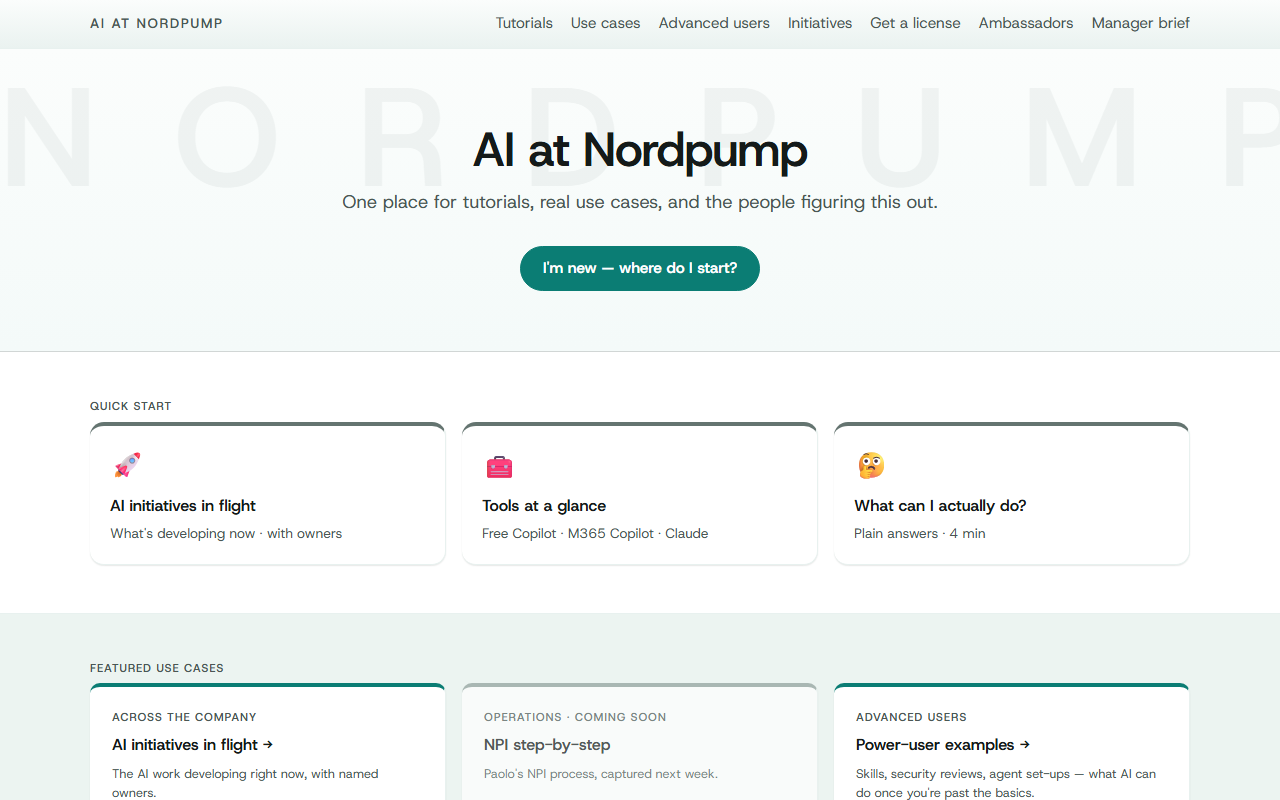
Internal AI adoption hub with tutorials, use cases, ambassador programme and manager brief anonymized demo
Case 02 AI programme

AI Adoption Hub

AI projects were scattered across teams — no governance, no continuity.

Problem

No GDPR clearance process, no shared playbook, and no plan for what happens when the AI lead departs.

Value

A repeatable AI adoption playbook and a clean, documented handover — the initiative survives personnel changes.

What we built

Ran the AI programme as a tracked project: ambassador programme, GDPR/DPIA clearance guides, an AI setup tutorial on the intranet, and a final deliveries register designed for successor handover.
ambassador programme GDPR/DPIA guides handover register
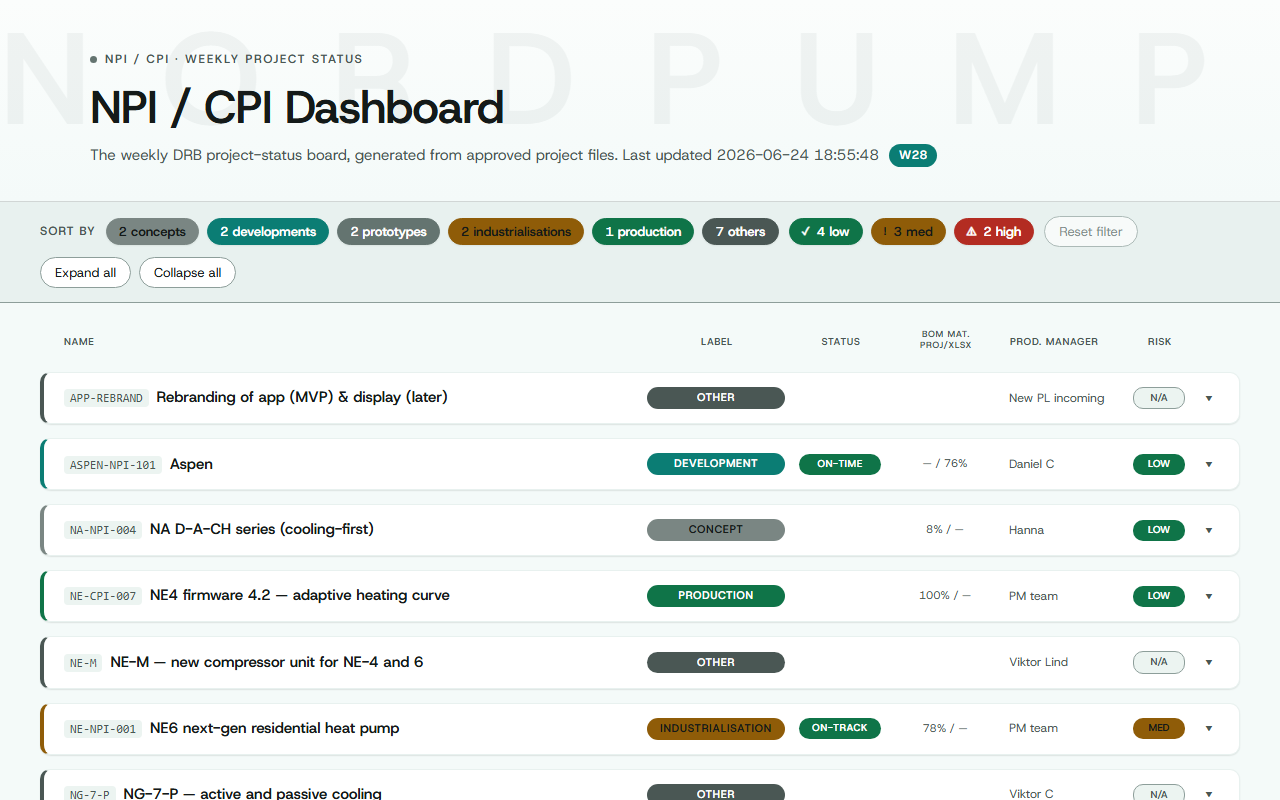
NPI/CPI project status dashboard rendered as status cards with labels, risk and progress anonymized demo
Case 03 PMO

Project Status Dashboard

Project status lived in a fragile Excel only engineers could run.

Problem

The portfolio status file was maintained by engineers; PMs couldn’t operate it themselves and the data went stale between updates.

Value

Lower-maintenance, error-resistant status reporting that PM owners operate independently — no engineer in the loop.

What we built

Replaced the Excel layer with a static-HTML dashboard generated from flat text files and live issue-tracker cards, designed for non-engineer PM owners. Pure-stdlib render pipeline, full test suite.
static HTML flat text files issue-tracker cards 40 passing tests
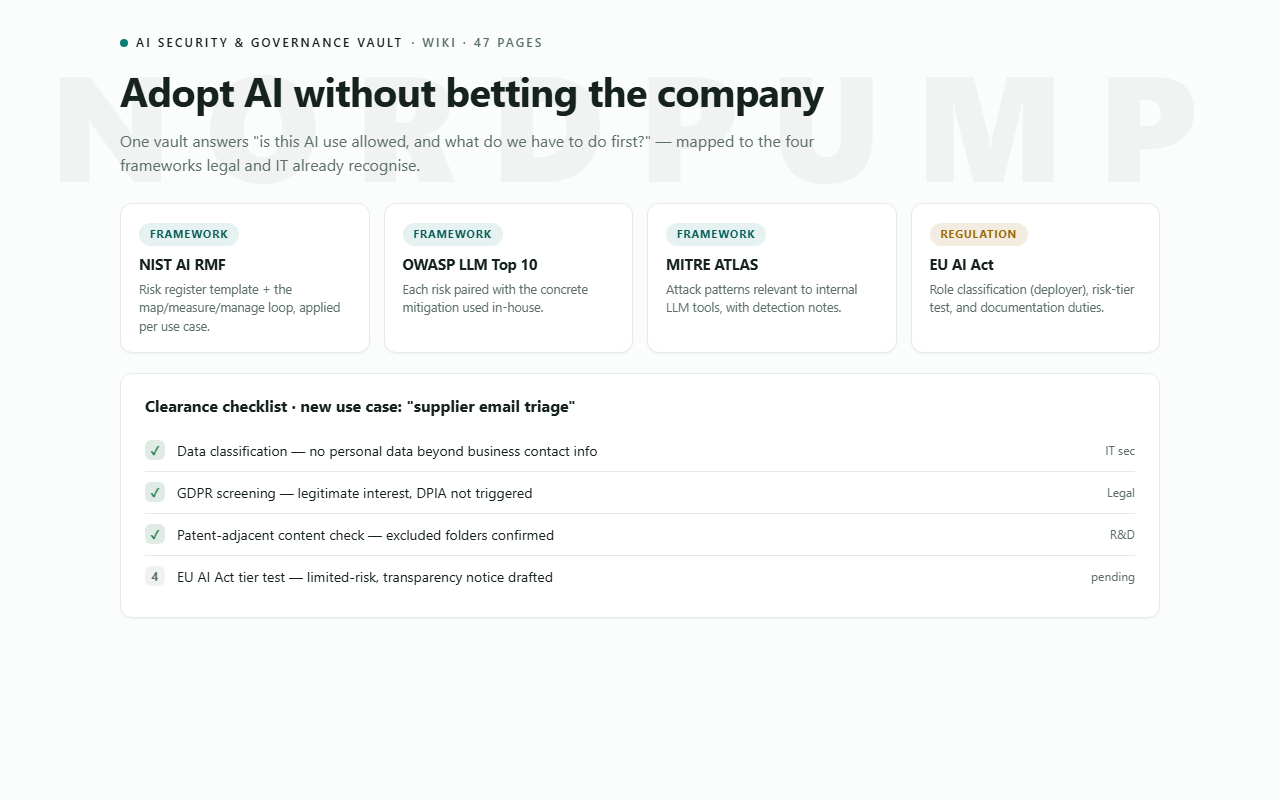
AI governance vault: NIST AI RMF, OWASP LLM Top 10, MITRE ATLAS and EU AI Act cards above a clearance checklist anonymized demo
Case 04 Governance

AI Governance Vault

No framework for adopting AI safely with sensitive data.

Problem

Compliance risk was undefined for AI use near sensitive or patent-adjacent data — so every use case stalled at “can we even do this?”.

Value

A governance and compliance foundation that enables safe enterprise AI adoption without regulatory exposure.

What we built

A compliance wiki aligned to NIST AI RMF, OWASP LLM Top 10, MITRE ATLAS and the EU AI Act — with per-use-case clearance checklists.
NIST AI RMF OWASP LLM Top 10 MITRE ATLAS EU AI Act
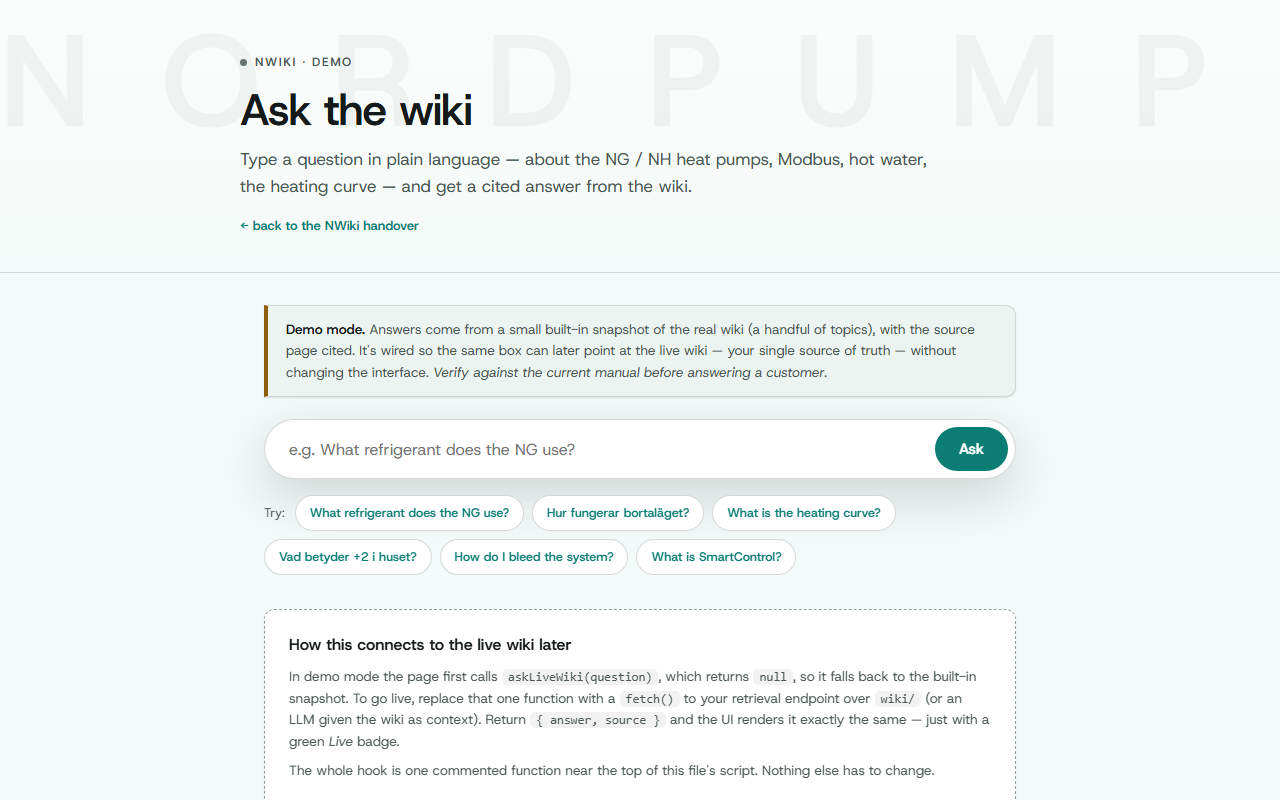
Ask-the-wiki chatbot demo answering plain-language product questions with cited sources anonymized demo
Case 05 Support

Support Chatbot

Support spent hours answering questions the docs already answered.

Problem

The answers existed in the knowledge base — they just weren’t quickly findable when a customer was waiting on the line.

Value

Proved the knowledge base could power frontline Q&A — a working assistant for support staff from day one, with cited sources.

What we built

A Python chatbot answering from the product knowledge base via the Anthropic SDK, with prompt caching holding the full ~180 KB corpus in context.
Python Anthropic SDK prompt caching
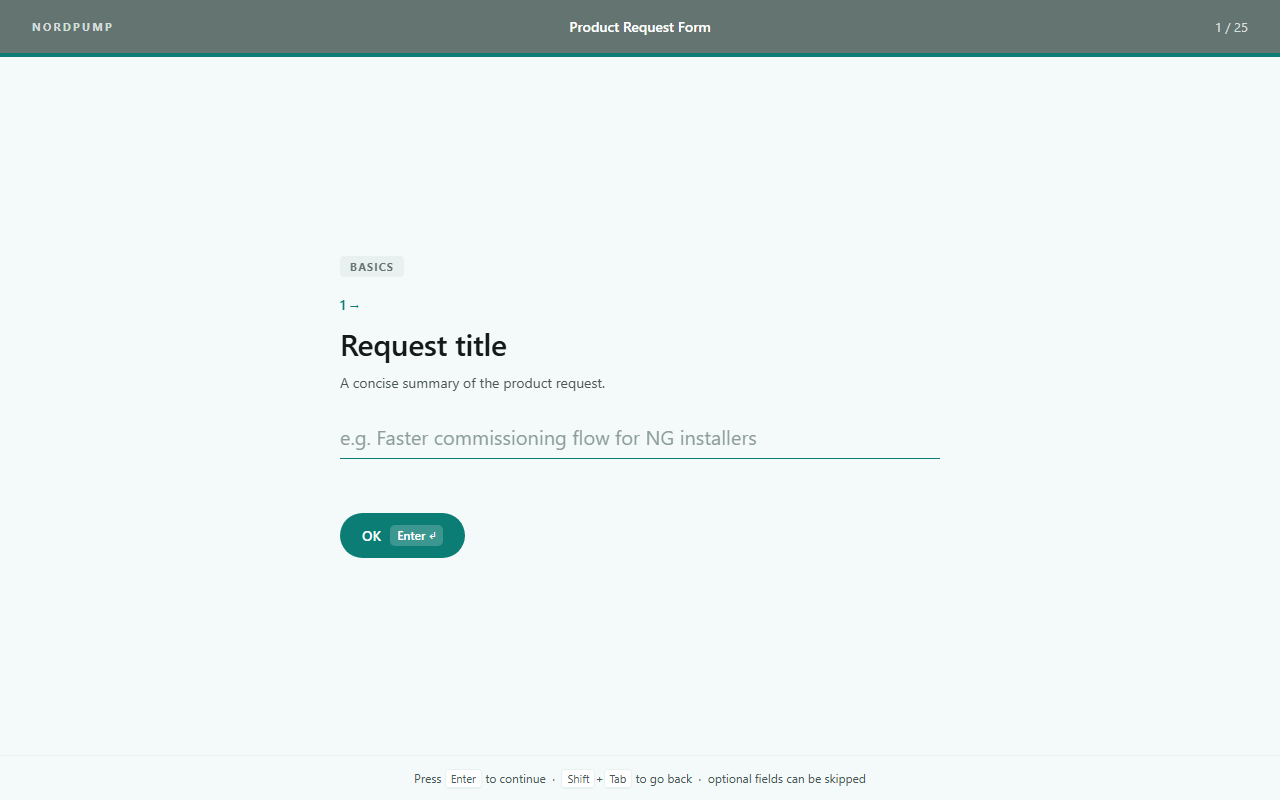
Keyboard-first multi-step form: one question per screen, Enter to continue, progress 1 of 25 anonymized demo
Case 06 UX build

Keyboard-First Onboarding Form

Long, linear onboarding flows lost people before the end.

Problem

Friction-heavy intake: long forms, no flow, drop-off before completion.

Value

A reusable UI prototype demonstrating rapid build capability — and a template for future onboarding flows.

What we built

A keyboard-first multi-step web form — one question per screen, Enter to continue — Playwright-verified and shipped in a single sprint.
keyboard-first multi-step Playwright-verified one sprint
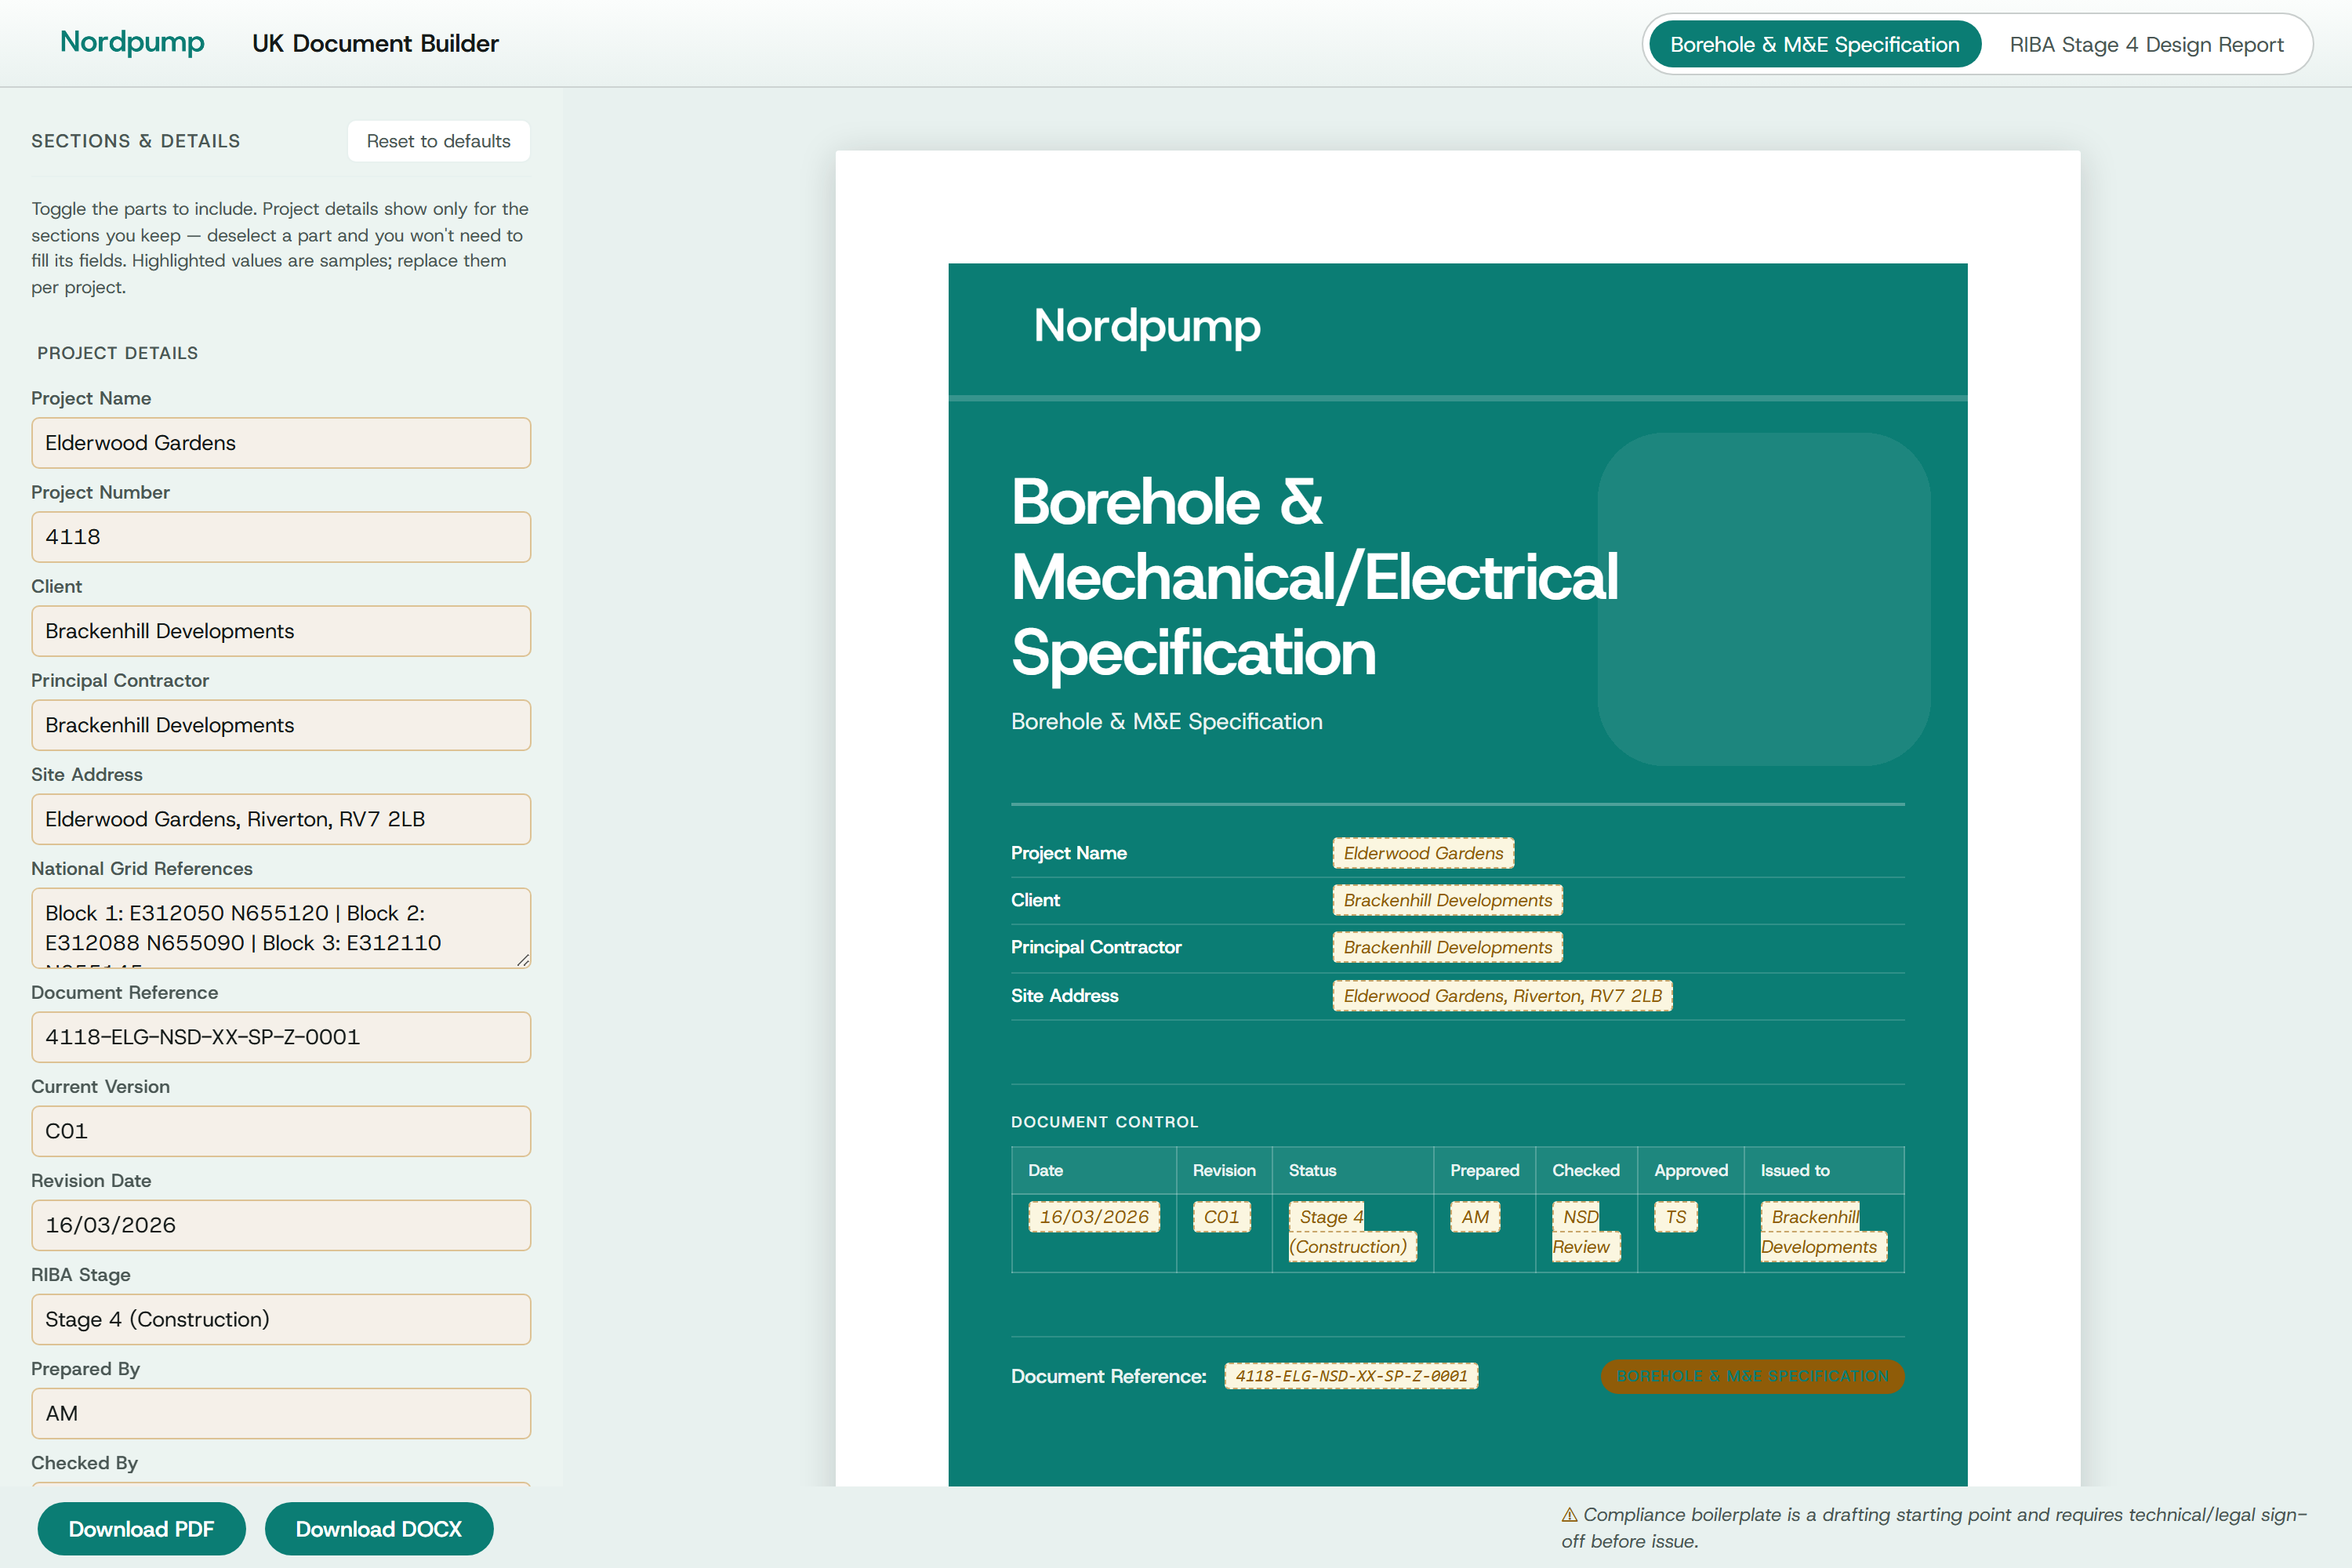
Browser-based compliance document builder: pick document type, toggle sections, live A4 preview anonymized demo
Case 07 Compliance tooling

Compliance Document Builder

Every engineering compliance document was built from scratch by hand.

Problem

Borehole/M&E specs and RIBA Stage 4 design reports — each one a full day of manual drafting against UK Building Regs, HNTAS and CP1 citations.

Value

A day of drafting collapsed into an hour, with a live preview so nothing is exported until it's actually right.

What we built

A browser-based, no-server document builder: pick the document type, toggle the sections a given project needs, edit live, and export straight to PDF or Word.

no-server tool live preview PDF / Word export
“Compliance documents used to eat a full day each — Borehole and M&E specs, RIBA Stage 4 reports, all built by hand against UK Building Regs, HNTAS and CP1 citations. Jacob built a tool where I pick the document type, toggle the sections I need, and get a live preview as I go. What took a day now takes an hour, and the export is ready — PDF or Word.” Michael M · Director, Energy Solution Design
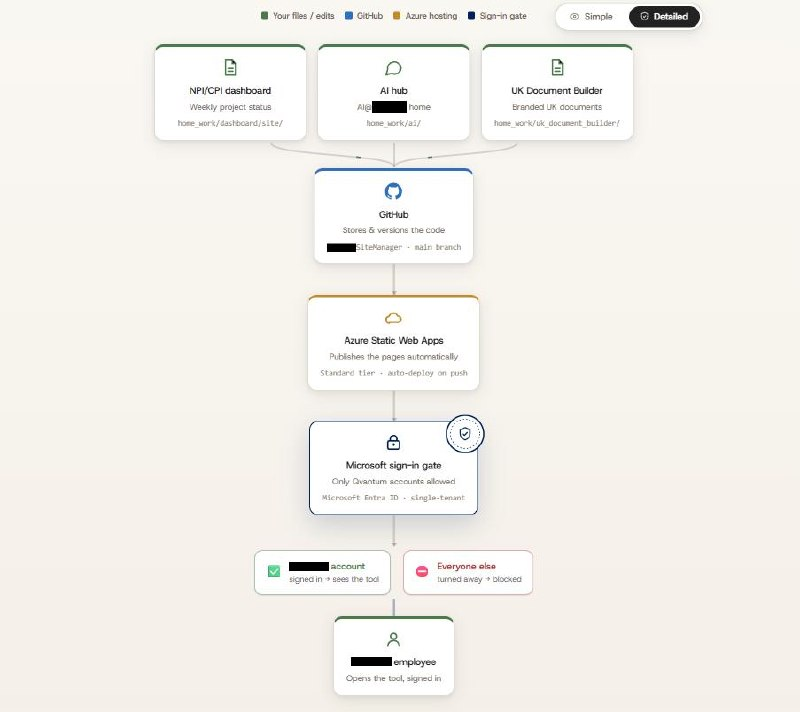
Architecture diagram: three internal tools push to GitHub, Azure Static Web Apps auto-deploys, a Microsoft Entra ID sign-in gate lets only company accounts through anonymized demo
Case 08 Platform & identity

Sign-in & Hosting Pipeline

Every internal tool needed its own login screen and its own manual deploy.

Problem

Three internal tools, three ad-hoc ways to keep outsiders out — and every release meant someone manually pushing files to a server.

Value

One sign-in gate for every tool, and every release ships itself — no build servers to babysit, no manual deploy step to forget.

What we built

A single-tenant Microsoft Entra ID app registration gating three internal tools — only company accounts pass, everyone else is bounced to sign-in. Paired with a GitHub → Azure Static Web Apps pipeline: push to main, GitHub Actions deploys it automatically, live in 1–2 minutes. Every permission, redirect URI and secret wired end to end.

Microsoft Entra ID Azure Static Web Apps GitHub Actions auto-deploy on push
“Jacob set up single sign-on for three of our internal tools through a proper Microsoft Entra app registration, so only our own company accounts get in. He also built the publishing pipeline — push to GitHub, Azure deploys it automatically, no build servers to babysit. And he got every permission and secret wired correctly so it worked end to end.” Dominic · Revenue Operations Manager

Roadmap

scoped · not yet built

Systems designed and scoped for this customer — concept visuals, not shipped software.
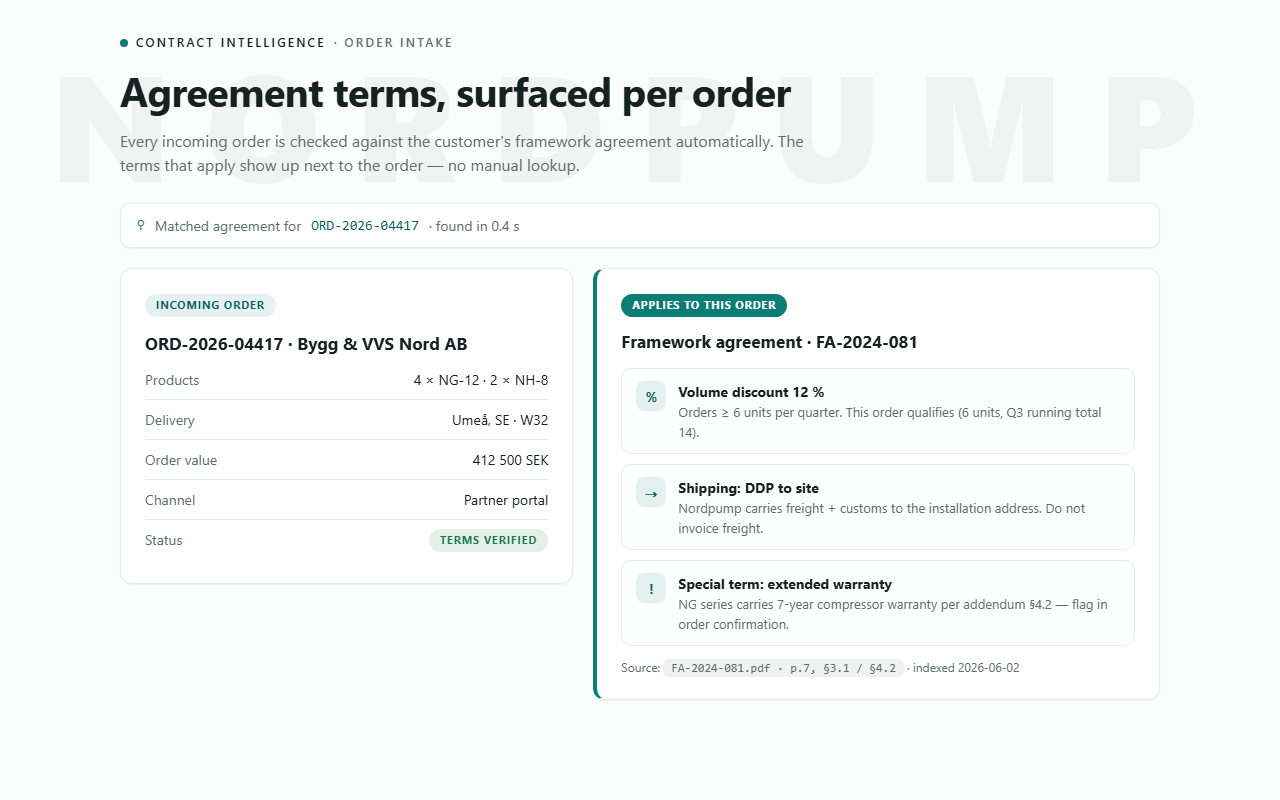
Concept: order intake screen where the matching framework agreement's terms are surfaced next to an incoming order concept visual
Roadmap 01 Sales ops

Contract Intelligence

Every order means digging through customer agreements by hand.

Problem

Sales ops manually check agreements for each incoming order — shipping rules, discounts, special terms buried in dozens of contracts.

Value

Eliminates slow, error-prone manual lookup — order processing becomes self-correcting, the right terms surface themselves.

Planned build

Index all customer contracts into a searchable knowledge base; incoming orders auto-query the matching agreement and surface the terms that apply.
contract index auto-lookup order intake
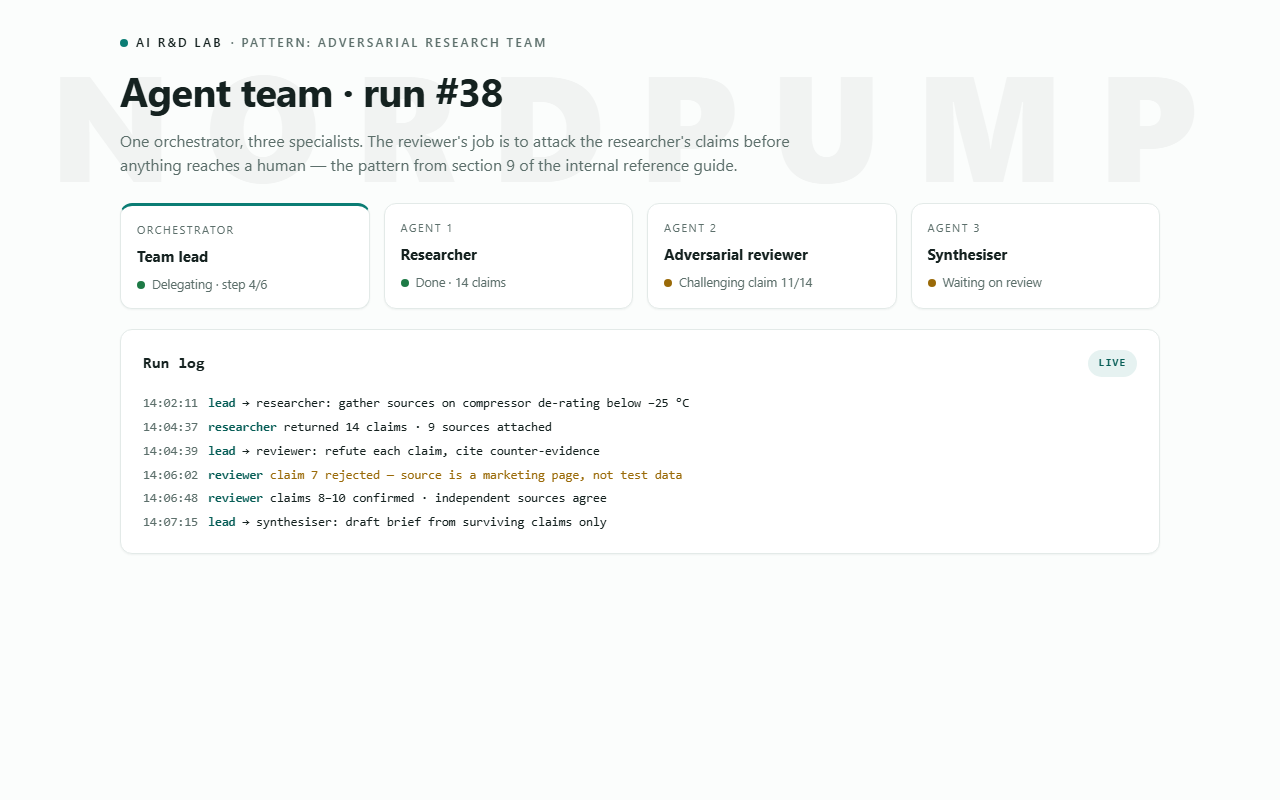
Concept: multi-agent run console with orchestrator, researcher, adversarial reviewer and synthesiser concept visual
Roadmap 02 R&D enablement

Multi-Agent Patterns Lab

Teams build agent workflows ad-hoc, duplicating effort.

Problem

No internal understanding of how to structure AI agent workflows — every team starts from zero and repeats the same mistakes.

Value

Internal capability-building: best-practice patterns teams adopt immediately instead of reinventing them.

Planned build

Stress-test multi-agent LLM workflows: an internal reference guide, an adversarial research-team pattern, and a demo app built end-to-end by parallel agents.
reference guide adversarial review parallel agents
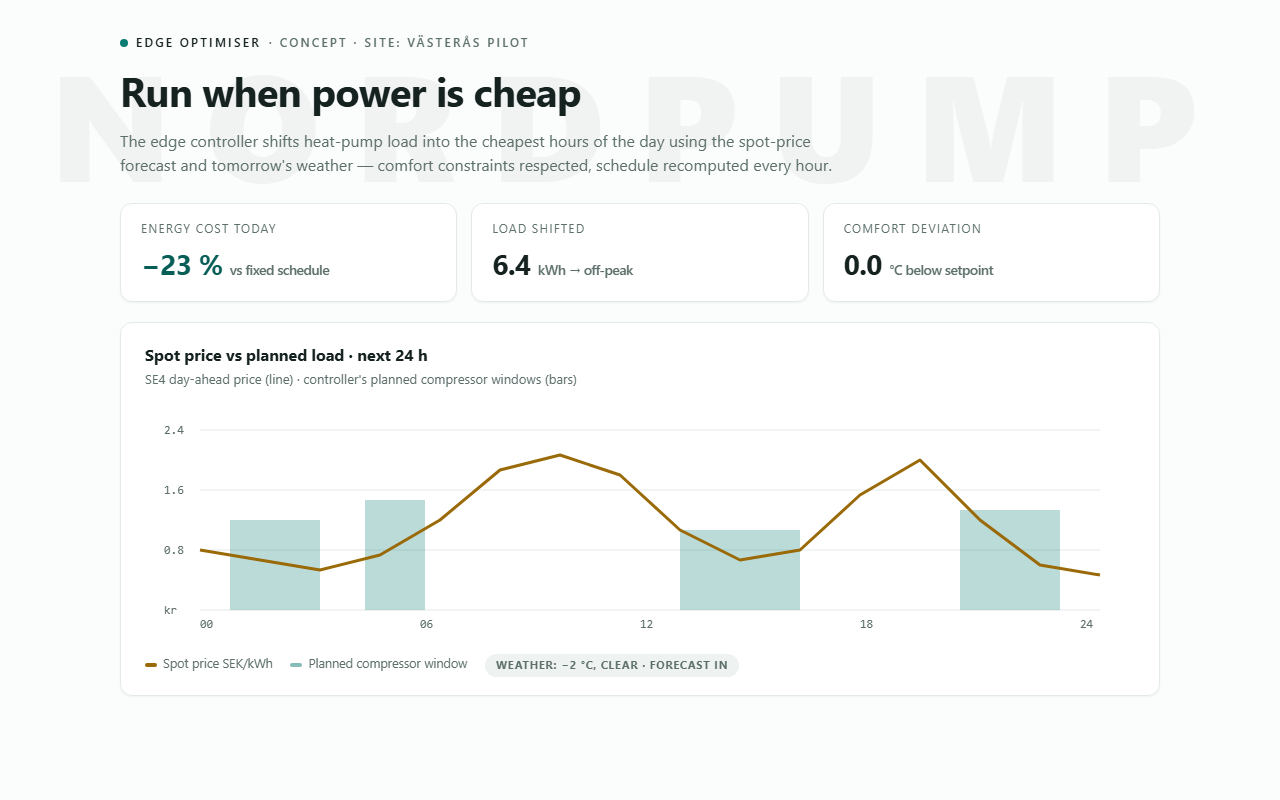
Concept: edge controller dashboard with spot price curve, planned compressor windows and savings KPIs concept visual
Roadmap 03 Innovation

Edge Energy Optimiser

Hardware runs on fixed schedules, blind to electricity prices.

Problem

Units ignore live spot prices and weather forecasts — unnecessary energy cost for every installed customer, every day.

Value

An energy-cost differentiator — an innovation concept with engineering questions ready for R&D.

Planned build

An edge controller that dynamically optimises hardware operation against spot prices and weather: 3-phase roadmap, fieldbus data capture, European rollout plan.
edge controller spot prices 3-phase roadmap
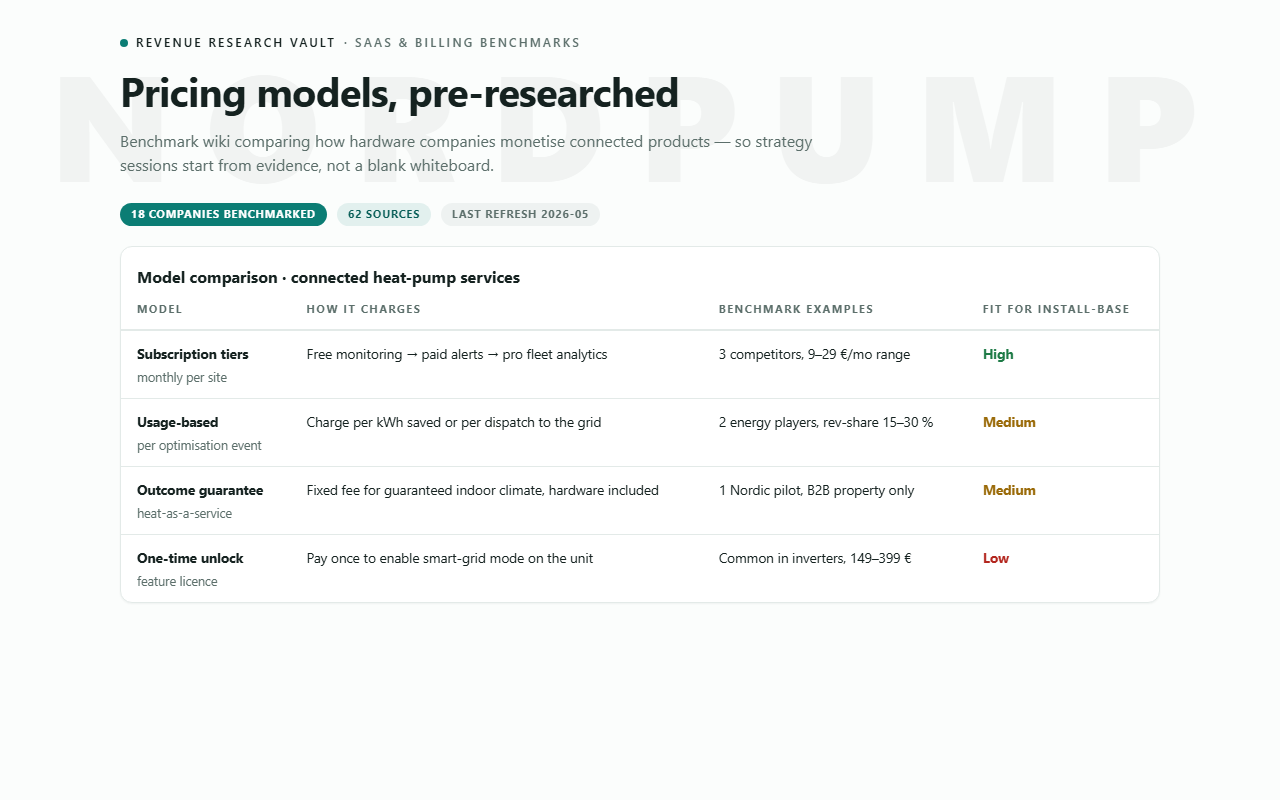
Concept: SaaS revenue benchmark wiki comparing pricing models for connected products concept visual
Roadmap 04 Strategy

Revenue Benchmark Vault

Every pricing discussion starts from a blank whiteboard.

Problem

No structured benchmarks for SaaS billing and revenue models — strategy conversations restart the research each time.

Value

Rapid, reusable research assets that cut preparation time for strategic and pricing discussions.

Planned build

Structured benchmark wikis on SaaS revenue and billing models for competitive research and pricing decisions.

benchmark wikis pricing models competitive research

Want one of these inside your company?

I scope one constraint at a time, build the AI system to remove it, and measure the before/after.

Work with us →
Builds in public

Real constraints removed. Real KPIs moved.

The systems behind the channel itself. Each build follows one framework: the thinking constraint that was blocking progress, the KPI that measures the improvement, and the AI system that solved it. The method: Constraints removed, KPIs moved.

Thinking constraint
KPI (before → after)
Build
Build 01 Publishing

Episode pages were a manual 2–4 h job blocking every publish

Thinking constraint

Building each episode page took 2–4 hours of focused writing + assembly. I couldn't publish without being present and uninterrupted.

KPI
0 h

Jacob-time per episode build. AI reads the brief and builds the page unsupervised overnight.

Build

Nightly engine: claude -p runs on a Task Scheduler cron. It reads a brief I drop at 20:30, asks clarifying questions via Telegram, then builds the full episode HTML and leaves a morning handoff note.

claude -p cron Telegram nightly briefs
Build 02 Research

Evaluating a tutorial video took 20 minutes of passive watching

Thinking constraint

Before I could use a video’s claims in content I had to sit through the whole thing — a gating step on every piece of research.

KPI
20 min → 3 min

Extract + full fact-check. Found income claims were 4× inflated vs. real market rates.

Build

The /watch skill: yt-dlp downloads, ffmpeg extracts 80 frames, Whisper transcribes 565 segments, then three parallel research agents cross-verify the claims against external sources.

/watch skill yt-dlp ffmpeg Whisper parallel agents
Build 03 Infrastructure

AI agents couldn’t read the site — every site-aware automation was blocked

Thinking constraint

The site was built for human eyes. Agents scraped it badly and missed key content, blocking any workflow that needed site context.

KPI
1 command

npx github:tellingtechnology/tellingtech-mcp — any AI reads the entire site from a single call, in full context.

Build

llms.txt manifest, JSON site index, an npm CLI package, and an MCP server — so any Claude instance can query the full site content without touching the HTML.

llms.txt JSON index MCP server npm CLI
Build 04 Observability

Context filling was invisible — sessions died with no warning

Thinking constraint

Long sessions degraded silently as context filled. I only noticed when output quality dropped — too late to act cleanly.

KPI
0

Silent context deaths. Two live token bars in the terminal show exactly when to /compact before quality drops.

Build

statusline.js — a Node script that polls Claude Code’s internal session state and renders a real-time cockpit bar: model, effort level, context fuel, and session-token fuel.

statusline.js Node Claude Code hooks
Build 05 In-house consulting

The team’s AI-fixable problems had no owner — they kept piling up

Thinking constraint

Colleagues hit repetitive bottlenecks they didn’t know AI could remove. No one on the team could diagnose the problem, let alone prescribe a fix.

KPI
Inbound ↑

Colleagues now bring problems to me. Went from nobody knowing who to ask → the team’s default first call for anything AI-shaped.

Build

No single artifact — the pattern. Applied constraint-first thinking inside one complex product company: audited real blockers, shipped targeted fixes, measured before/after. Results visible to the team compounded into trust.

constraint audit internal consulting in-house AI role
“I’m not going to find this job on LinkedIn — because it doesn’t exist yet.”
Build 06 Data platform

“How close to transit” and “can I still connect” were both guesses — now they’re one API

Thinking constraint

Two real Skåne questions with no honest answer available: which electric-grid areas are heading for a build-stop before you commit to a connection, and whether a “15 minutes to transit” claim on a property listing means anything real, stop by stop.

KPI
165 · T50/T90

165 grid companies mapped, 74 of 141 already build-stopped today. On the transit side, two numbers instead of one — the typical trip time and the one you actually have to plan around.

Build

Built with Bengt: one engine, two data layers, one API key with per-layer access. Nätplansradarn reads every Swedish grid company’s own development plan and turns it into a live capacity map. TransitTrue simulates hundreds of possible departures per stop from real Skånetrafiken GTFS data instead of guessing from straight-line distance. Piloted on Lomma→Malmö C, ready to scale to the rest of Skåne.

real GTFS + grid-plan data one API, two layers R5 routing pilot live
Build 07 Personal context

Your prompts are only as good as the context you never wrote down

Thinking constraint

Every AI answer improves with context — your files, your calendar, the people and plans around you — but almost nobody keeps that anywhere an AI can read it. Building it by hand is exactly the kind of thing people mean to start and never do.

KPI
Your data, portable

One command hands you everything stored about you as plain markdown — the same files your own assistant reads — ready to drop straight into a Claude or Codex project.

Build

Pocket Operator: a private, invite-only AI assistant with Cortex, its memory system, built in. Send /brain and it asks five questions once — who you are, what you're on, how you like answers, your world, your rules — then writes it to plain text files it re-reads every reply, forever, on any device. Say “export my data” any time and everything ships as files you own, ready to drop into a Claude or Codex project. It's the on-ramp: start collecting your own context somewhere simple, so any AI you use afterward — here or elsewhere — already knows more about you than a blank prompt.

/brain, five questions plain markdown, no lock-in export my data invite-only beta

Next build

Constraint and KPI get defined first, build second. New builds land here as the episodes ship.

Constraint → KPI → build

Need a constraint removed in your company?

I scope one constraint at a time, build the AI system to remove it, and measure the before/after.

Work with us →